
Multi-agent co-design and polycentric governance of open educational commons – a living lab model
Multi-agent co-design and polycentric governance of open educational commons – a living lab model
André Boeing, Sept 26th 02026
Since 2022, I have been experimenting with an alternative model for developing Open Educational Resources (OER) and programs in multi-stakeholder collaborations involving diverse agents from municipal, governmental, non-profit, and non-governmental organizations, as well as freelancers, people with disabilities, youth, elders, and students.
I had not previously formalized the model, having only shared graphical sketches accompanied by loose notes two years ago. Inspired by the rich framework presented in the open course ScaDaMaLe (Scalable Data Science and Distributed Machine Learning by Dr. Raazesh Sainudiin), I have finally found the building blocks and “eureka moments” needed to advance this work. This now provides a descriptive language for the model through which we have been co-developing programs in practical living labs over the past three years. What applies to human agents in the following sections might also apply to digital machine agents.
This does not seem strange to me, as AI models originate from human cultural, social, and collective intelligence—and perhaps even from a “faculty of agency itself.” Whether “natural” or “artificial,” these collective intelligent systems move us forward as we continue to explore what intelligence is and could be.
Based on decades of experience designing educational programs and formats, I have found that the classic top-down hierarchical model—and the deterministic, centralized control systems it entails—is often inefficient and slow. More critically, it hinders agility, preventing Education for Sustainable Development (ESD) innovation projects from flourishing and adapting in real time as conditions inevitably shift during living lab development.
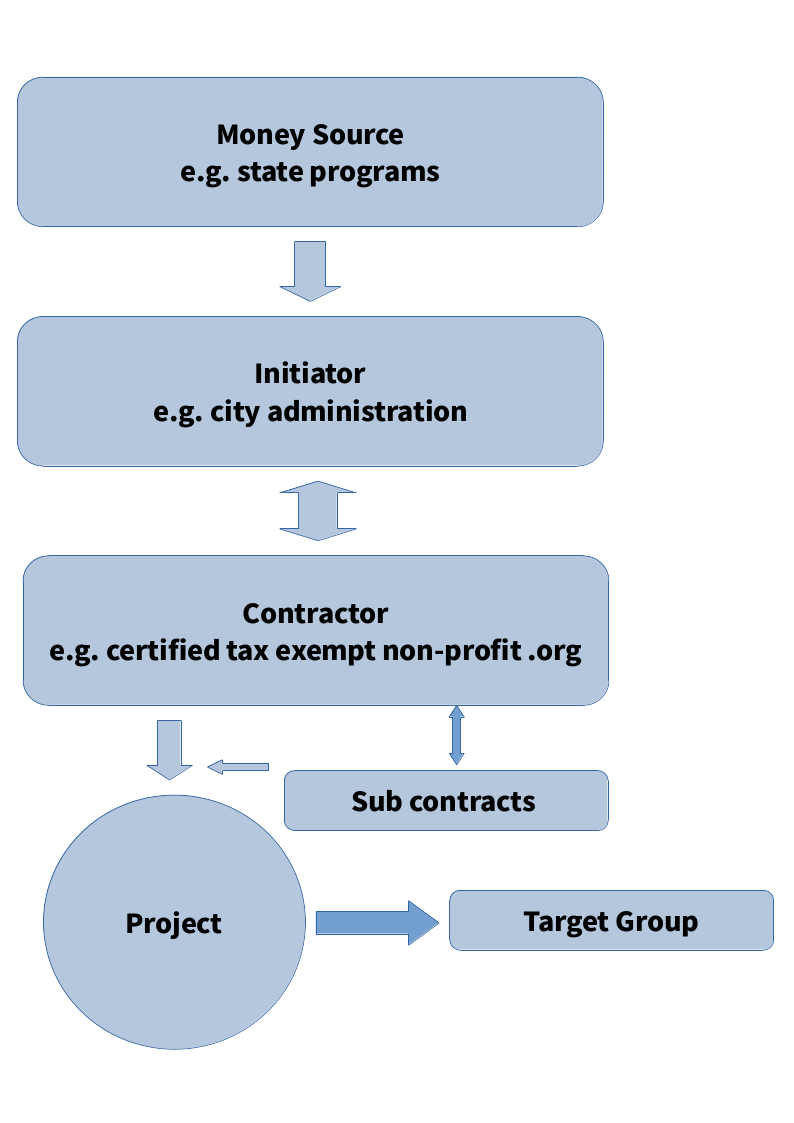
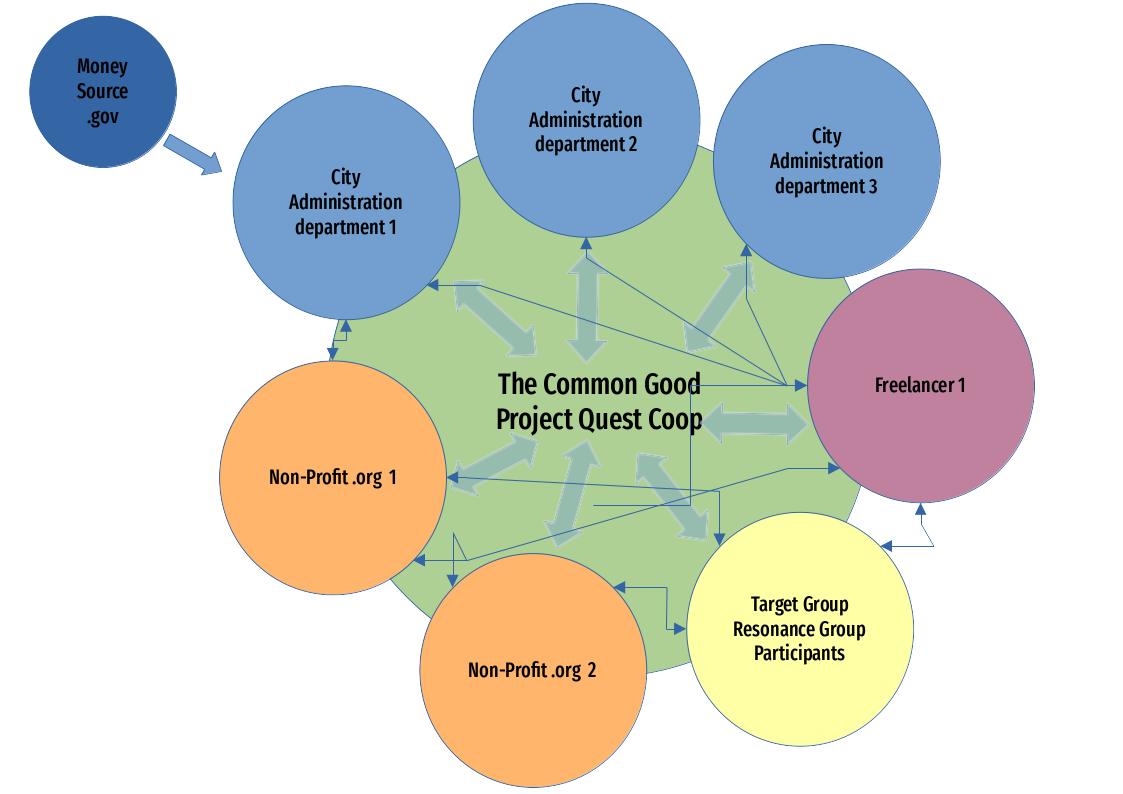
Decentralized, adaptive, and feedback-driven systems enabled our transition from optimization under plan-driven certainty (which frequently proved unviable, as the assumed “certainty” often reflected wishful thinking or even “hallucination”) to learning under uncertainty—a capacity that cultivates organizational resilience.
Professor Michael I. Jordan’s work on Multi-Agent Reinforcement Learning (MARL) provided a theoretical framework that further crystallized my practical insights: by treating stakeholders—including “target groups”—as autonomous, sovereign agents optimizing shared objectives, the system naturally evolved toward relational stewardship rather than transactional control. This approach continues to unfold in our ongoing living-lab project at fsysgame.org
And then Elinor Ostrom’s work pushed my buttons in a good way and unlocked the “missing in plain sight puzzle piece.” On my often euphoric, positive, and sometimes euphemistic side, my model assumed harmony—just because the model is beautiful. Ostrom also emphasizes how disputes are handled!
Disputes, conflicts, and frictions do come up when collaborating over many months with diverse, multi-stakeholder agents in intense production sprints! Multi-stakeholder systems do imply epistemic diversity and methodological divergence as a feature! Our own home planet, with its marvelous, homeostatic, biodiverse system, is the perfect proof of a regenerative, incredibly long-lived system. We do well to relearn from it. Real living labs with real impact value are rarely created behind desks or in sterile labs!
So—friction is not a failure; it is a signal that the commons is adapting to complex, pluralistic contexts. A conflict resolution system provides a transparent, graduated, and non-punitive pathway to resolve disagreements, align competing narratives, and adjust contributions without breaking relational trust or halting co-creation.
From what I have now learned, we could treat conflict as predictive error (Jordan/MARL), institutional stress (Ostrom), and incentive misalignment (Contract Theory) and could focus on proportional response, evidence-based adjustment, and relational healing!
A common reaction I have noticed among many multi-stakeholder agents during some projects and years is a strange belief that says something like this: “Conflict and friction are failures that cost lots of energy and stress, and they were also not part of our agreement plan. The way to solve this is to not talk about it, with a shared commitment to non-communication in this regard. Time eventually makes the conflicts obsolete—at the latest after the project is finished and the conflicting parties part ways anyway (even before any impact goals beyond the funded project timeframe could be achieved).”
Elder Elinor Ostrom offers a graduated pathway for these shadow yet natural sides of collaboration:
🪜 The 4-Tier Graduated Pathway
Note: “Sanctions” = temporary loss of influence + mandatory re-alignment, not banning. The goal is systemic convergence, not compliance.
Lets sum up with the three ingredients and components for the model: “Contract Theory in Practice”, “Elinor Ostroms 8 Principles” and “Michael I. Jordans Multi-Agent Reinforcement Learning (MARL)”
1. Contract Theory: From IP Control to Open Relational Pacts
Traditional OER projects often collapse under the tension between open licensing and closed funding/contracting. Our experimental model solves this by shifting from transactional contracts to relational contribution agreements:
-
Incentive Realignment: Creators aren’t paid for exclusivity; they’re incentivized by pedagogical impact, network access, reputation, co-development priority or just a “good time during Playshops and Fun”.
-
Monitoring via Usage & Peer Review: Instead of compliance audits, we began to track open metrics: module adoption, teacher adaptation rates, player engagement, etc. in our latest fsysgame.org project.
-
Dynamic Obligations: Contracts become living contribution charters. If – for example – a freelancer’s game module underperforms pedagogically, the network adapts (patches, co-revisions, role shifts) rather than terminating agreements.
2. Ostrom’s Principles: Governing the Educational Knowledge Commons
Our OER/ESD game suite is a commons. Ostrom’s 8 principles map directly to sustainable open education ecosystems:
| Ostrom Principle | Our Implementation |
|---|---|
|
Clearly defined boundaries |
Creative Commons licensing + project scope + contribution guidelines |
|
Rules matching local conditions |
Modular game design: core ESD mechanics + regional/contextual scenarios (e.g., local water systems, urban mobility, circular economy pilots) |
|
Collective-choice arrangements |
Co-design workshops with teachers, students, NGOs, and city depts; voting on feature priorities & adaptation guidelines |
|
Effective monitoring |
Open analytics dashboards, classroom feedback loops, peer review of pedagogical efficacy |
|
Graduated sanctions/reputation |
Contribution weighting, co-development priority, public attribution, not punitive clauses |
|
Conflict resolution |
Community patch notes, transparent design rationale, mediated scenario disputes (e.g., competing ESD narratives) |
|
Nested enterprises |
Classroom → school → city education network → national OER repository → EU ESD framework |
|
Recognized rights to organize |
Teachers/freelancers/NGOs retain IP in their contributions while embedding them in the open commons |
👉 Why it works: OER/ESD games fail when treated as “products.” Our model treat them as living institutional infrastructures that self-correct through use.
3. Prof. Michael I. Jordan’s Lens: Games as Multi-Agent Learning Systems
Jordan’s work on probabilistic graphical models, multi-agent systems, and algorithmic governance reveals why our model is somewhat computationally elegant for ESD:
| Concept | How It maps to our Projects |
|---|---|
|
Multi-Agent Reinforcement Learning (MARL) |
Each stakeholder (teacher, student, freelancer, city dept) is an agent optimizing partial objectives. The game mechanics + feedback loops approximate shared policy iteration. |
|
Online/Continual Learning |
Player responses, classroom adaptation, and teacher feedback serve as real-time reward signals. Version updates = policy adjustments. |
|
Federated Development |
OER versioning mirrors federated learning: local nodes (schools, NGOs) adapt core modules without centralizing control. |
|
Shared Reward Function |
In education, this isn’t profit—it’s systems literacy, behavioral shift, and sustainable decision-making. Our model still needs to formalize this as measurable indicators. |
|
Hierarchical/Policy Abstraction |
Analogous to hierarchical RL: low-level mechanics (game rules) → mid-level pedagogy (teacher facilitation) → high-level ESD outcomes (policy alignment, community action). |
Raaz pointed me to a chapter that he thought might really interest me. And holy, was he right. Remember my growing discomfort with classic top-down, hierarchical models and deterministic, centralized control systems? From my practice experience, I’ve found them inefficient and slow—especially when they prevent Education for Sustainable Development (ESD) innovation projects from flourishing and adapting as living lab conditions naturally shift in real time.
I’ll let this post end with a beautiful, both scientific and poetic question and quest that Raaz invites us into through his practical group projects. Next week, I’ll share the story of what happened next—living it out in real, physical, rapid micro living labs way up in the Northern lands..
7. The IAS ladder: Part V hook
This section is clearly separated from the course exposition above and is intended for students
continuing into Part V (advanced seminars / group projects).The IAS (Identityless Agent Substrate) architecture models the operator–agent pairing as a
repeated principal-agent relationship. In each session:
• The principal is the human operator who cannot directly inspect the agent’s internal state
— only the observable outputs (commits, tool calls, design documents).
• The agent is the IAS-governed agent incarnation, whose behaviour is a function of its
specification and lineage.
• The type is the agent’s behavioural distribution over tasks — how reliably it follows the
specification under the operator’s prompting style.Across sessions, the principal is learning the agent’s type. Classical contract theory says the
principal’s posterior over type is the sufficient statistic for optimal contract selection once it has
been computed. The IAS question is: How do you compute and propagate this posterior when
agent incarnations are ephemeral and stateless?
✍️ Author’s Note & Transparency Statement
For this article, I collaborated with a self-hosted Qwen3.6-35B-A3B-FP8 model across research, analysis of the accompanying graphics, iterative feedback, and chapter-level discussions.
What I deliberately do not use the model for is writing. Writing is a verb—and a fundamentally human one. This process cannot be outsourced, automated, or shortcut. It must happen within our cellular bioware and nervous systems.
Writing is not merely about producing a publication-perfect draft. It is a deeply alchemistic process through which our conscious nervous systems crystallize, grow connections, and share exploration.
The model used in this collaboration is Qwen3.6-35B-A3B-FP8, a Mixture-of-Experts (MoE) architecture developed by Alibaba. With 35 billion total parameters and approximately 3 billion active per forward pass, it is optimized for efficient, high-fidelity chat and agentic workflows—featuring robust reasoning, vision capabilities, and sustained performance across long-document analysis and extended multi-turn dialogues.
All final prose, structural decisions, and theoretical framing remain my own. The model served as a thinking partner, not an author during the 12 hours production time in one day and two study days before to explore the landscape.


